

Teams often start improving a RAG (retrieval-augmented generation) system by adjusting prompts or changing the model. In practice, retrieval deserves attention first because the model cannot use evidence it never receives. The quality, freshness, and structure of the knowledge base shape what the retriever can find. That sets an upper limit on answer quality.
We’ve spent the last stretch building a document-ingestion RAG pipeline that parses PDFs, Word files, and meeting transcripts into an answerable knowledge base. Most accuracy problems we chased led back to retrieval, so that is where this article focuses.
Architecture Overview
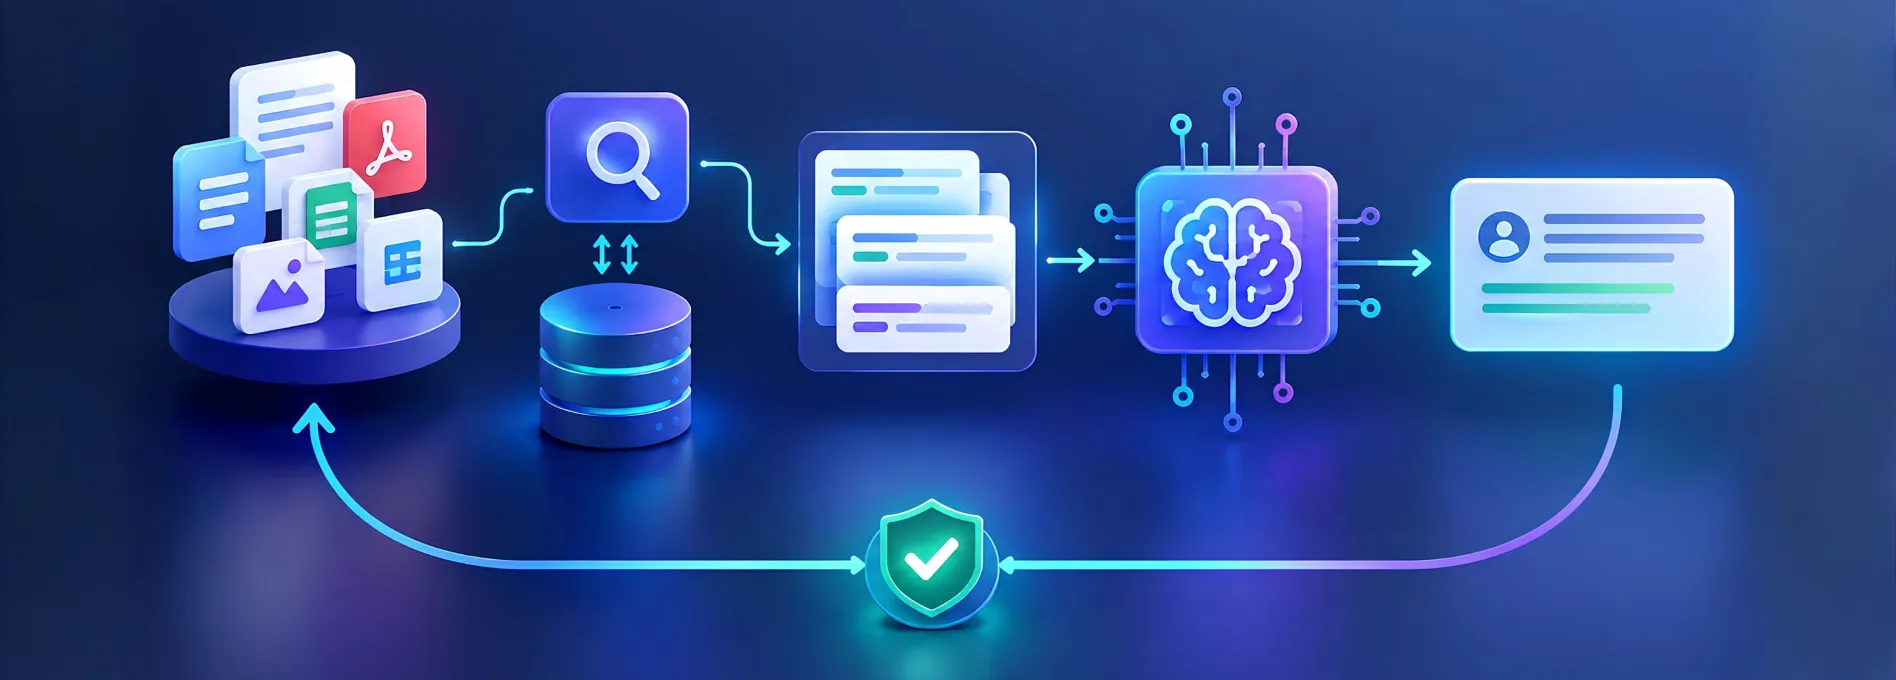
A typical production RAG pipeline looks like this:
Source ingestion → parsing and normalization → chunking → enrichment and indexing → candidate retrieval → filtering → reranking → context assembly → answer generation → validation and citation.
This sequence shows where each recommendation fits. It also helps less-experienced readers see where evidence can be lost or distorted.
Why is my RAG inaccurate? Look upstream of the model
Retrieval is where many RAG systems break, although generation, prompting, and response validation can fail on their own. Barnett and colleagues catalogued seven failure points in engineering a RAG system, including problems across retrieval, context handling, and answer generation. Start by identifying which stage failed before changing the model.
The quality of the knowledge base shows up directly in the answers. Atlan's analysis of RAG accuracy problems reports substantially higher retrieval accuracy on governed data than on ungoverned knowledge bases. Because Atlan sells governance tooling, treat its figures as vendor-reported rather than independent evidence. A 2025 study in JMIR Cancer found a similar pattern in a medical setting: chatbots grounded in a curated cancer-information source hallucinated less than chatbots using Google search results. The study supports constrained, reliable sources as a way to reduce hallucinations, while also noting trade-offs when the source does not cover a question.
A better model cannot rescue bad retrieval. Retrieval quality sets the ceiling, and the model works underneath it.
Chunking strategy for RAG is where quality is decided
Chunking decides what the model can see, which caps retrieval quality before search even runs. Split a document badly and you get fragments that match a query on the surface and contain nothing useful underneath.
Fixed-size chunking is a common source of retrieval problems because it can split related ideas across boundaries. A 2025 clinical study that changed only the chunking strategy found that chunks following the content's own structure gave far more accurate answers than fixed-token chunks. The question set was small and medical, so treat the size of the gain with care.
In our pipeline, we split on document structure, including headings, sections, and speaker turns. When a unit is too large for the budget, we split it again. We never split mid-sentence. We tried embedding-based topic detection early on and dropped it because it produced unpredictable, tiny fragments for some document types. Structural splitting was more consistent.
Format handling matters more than people expect. PDFs need column-order detection and tables extracted with their headers, or values lose the column they belonged to. Transcripts arrive as overlapping caption lines that have to be merged back into whole utterances before anything downstream can use them.
The most difficult failure was the silent one. Speech recognition and PDF table extraction can produce fluent, plausible text that is still wrong, and the extraction step may turn that noise into an apparent fact. We started scoring each unit for source confidence at parse time and passing the score into extraction. Low-confidence units are limited to clearly stated information rather than inferred details. Successful processing does not prove that the output accurately reflects the source.
Hybrid search in RAG fixes what dense vectors miss
Dense vector search can miss exact matches that keyword retrieval handles more reliably. Product codes, error strings, version numbers, and some proper names carry meaning in their literal tokens, so semantically similar passages can outrank the passage containing the exact term.
Hybrid search combines dense embeddings with sparse keyword retrieval such as BM25 (Best Matching 25), so conceptual questions and literal lookups can both work. It is a common production pattern because the two retrieval methods cover different failure modes.
There is a design choice inside hybrid search: what are you tuning for? We tune the first-stage retriever toward recall because a reranker can remove weak candidates later. A missed candidate never reaches the next stage, while an extra candidate mainly adds reranking cost and noise. The right balance still depends on latency, token budget, and the quality of the reranker.
Reranking turns a wide recall set into precision
Reranking is the second pass that trims a wide recall set down to what's actually relevant. You retrieve generously, then a stronger model reorders the candidates and keeps the best few for the prompt.
A 2026 benchmark on financial documents found that hybrid retrieval followed by a neural reranker beat every single-stage method it tested. That backs the recall-then-verify pattern many production systems settle on. How much you gain depends on your corpus, query mix, and reranker.
In our system the reranker is an LLM verification step. It checks each candidate from the wide recall pass and records why it kept or dropped it. That covers the job a cross-encoder reranker usually does, and the recorded reasons give us a trail we can audit later.
Context assembly preserves the evidence
Reranking selects the best candidates, but context assembly determines what the model finally sees. Deduplicate repeated passages, merge or trim overlapping chunks, and order evidence so related material stays together. Preserve structural relationships such as a table with its headers and a section with the heading that gives it meaning.
Context-window limits make this a budgeting problem, not a simple top-k cutoff. Reserve space for the instructions and answer. Prefer complete, high-value evidence over many fragments, and record which chunks were included or excluded. Otherwise, a strong retriever can still produce a weak prompt through duplication, broken context, or silent truncation.
Evaluate retrieval separately from generation
Retrieval evaluation and generation evaluation measure different failures, and a blended score hides both. If you only track end-to-end answer quality, a retriever that misses the right document looks fine whenever the model bluffs a plausible-sounding answer.
The RAGAS framework splits scoring along the same line. Context precision and context recall check what the retriever returned. Faithfulness and answer relevancy check what the model did with it. Scoring them separately tells you which stage to fix.
We learned this the hard way. In one version of our system, recall was silently capped by an index parameter (the ef_search setting on an HNSW, or Hierarchical Navigable Small World, index) because a version filter ran after the search instead of during it. Asking for 20 candidates could return about 4 on a project that had been edited ten times, and nothing logged that it happened. A short result looked exactly like a corpus that genuinely had little to say. Only a retrieval-specific test that checked whether a request for N candidates returned N caught the problem.
Barnett's team reached the same conclusion across three case studies: “validation of a RAG system is only feasible during operation.” Keep testing retrieval against real queries after launch.
Production monitoring should pair quality measures with operational ones. Track retrieval and reranking latency separately, along with the empty-result rate, stale-content retrieval rate, and cost per query. Break these metrics down by corpus, query type, and pipeline version so averages do not hide a failing segment.
Governance closes part of the loop. When a fact is superseded, retire or version it so stale content is less likely to be retrieved with high confidence. Record provenance at ingestion time so an answer can be traced to the source document and chunk that supported it. These controls improve auditability, although they do not by themselves prove that the source is correct.
Enterprise governance must also enforce authorization during retrieval. Carry document-level permissions into the index, filter candidates for the requesting user before reranking or generation, and test for cross-user and cross-tenant exposure. Permissions enforced only in the user interface are not enough.
Treat retrieved text as untrusted data rather than instructions. Defend against prompt injection embedded in documents, minimize sensitive information sent to the model, and redact or block protected data where policy requires it. Log access decisions and cited sources without exposing restricted content in diagnostics.